Data Lakehouse vs Data Warehouse for Enterprise AI: Which Architecture Should You Choose?
Your data architecture decision now sets a ceiling on what your AI programme can achieve. Pick the wrong foundation, and every new machine learning use case stalls behind infrastructure work rather than model development. This guide compares the data lakehouse vs data warehouse choice specifically through the lens of enterprise AI, so you can match the architecture to your workloads, your governance obligations, and your budget.
What is the difference between a data lakehouse and a data warehouse?
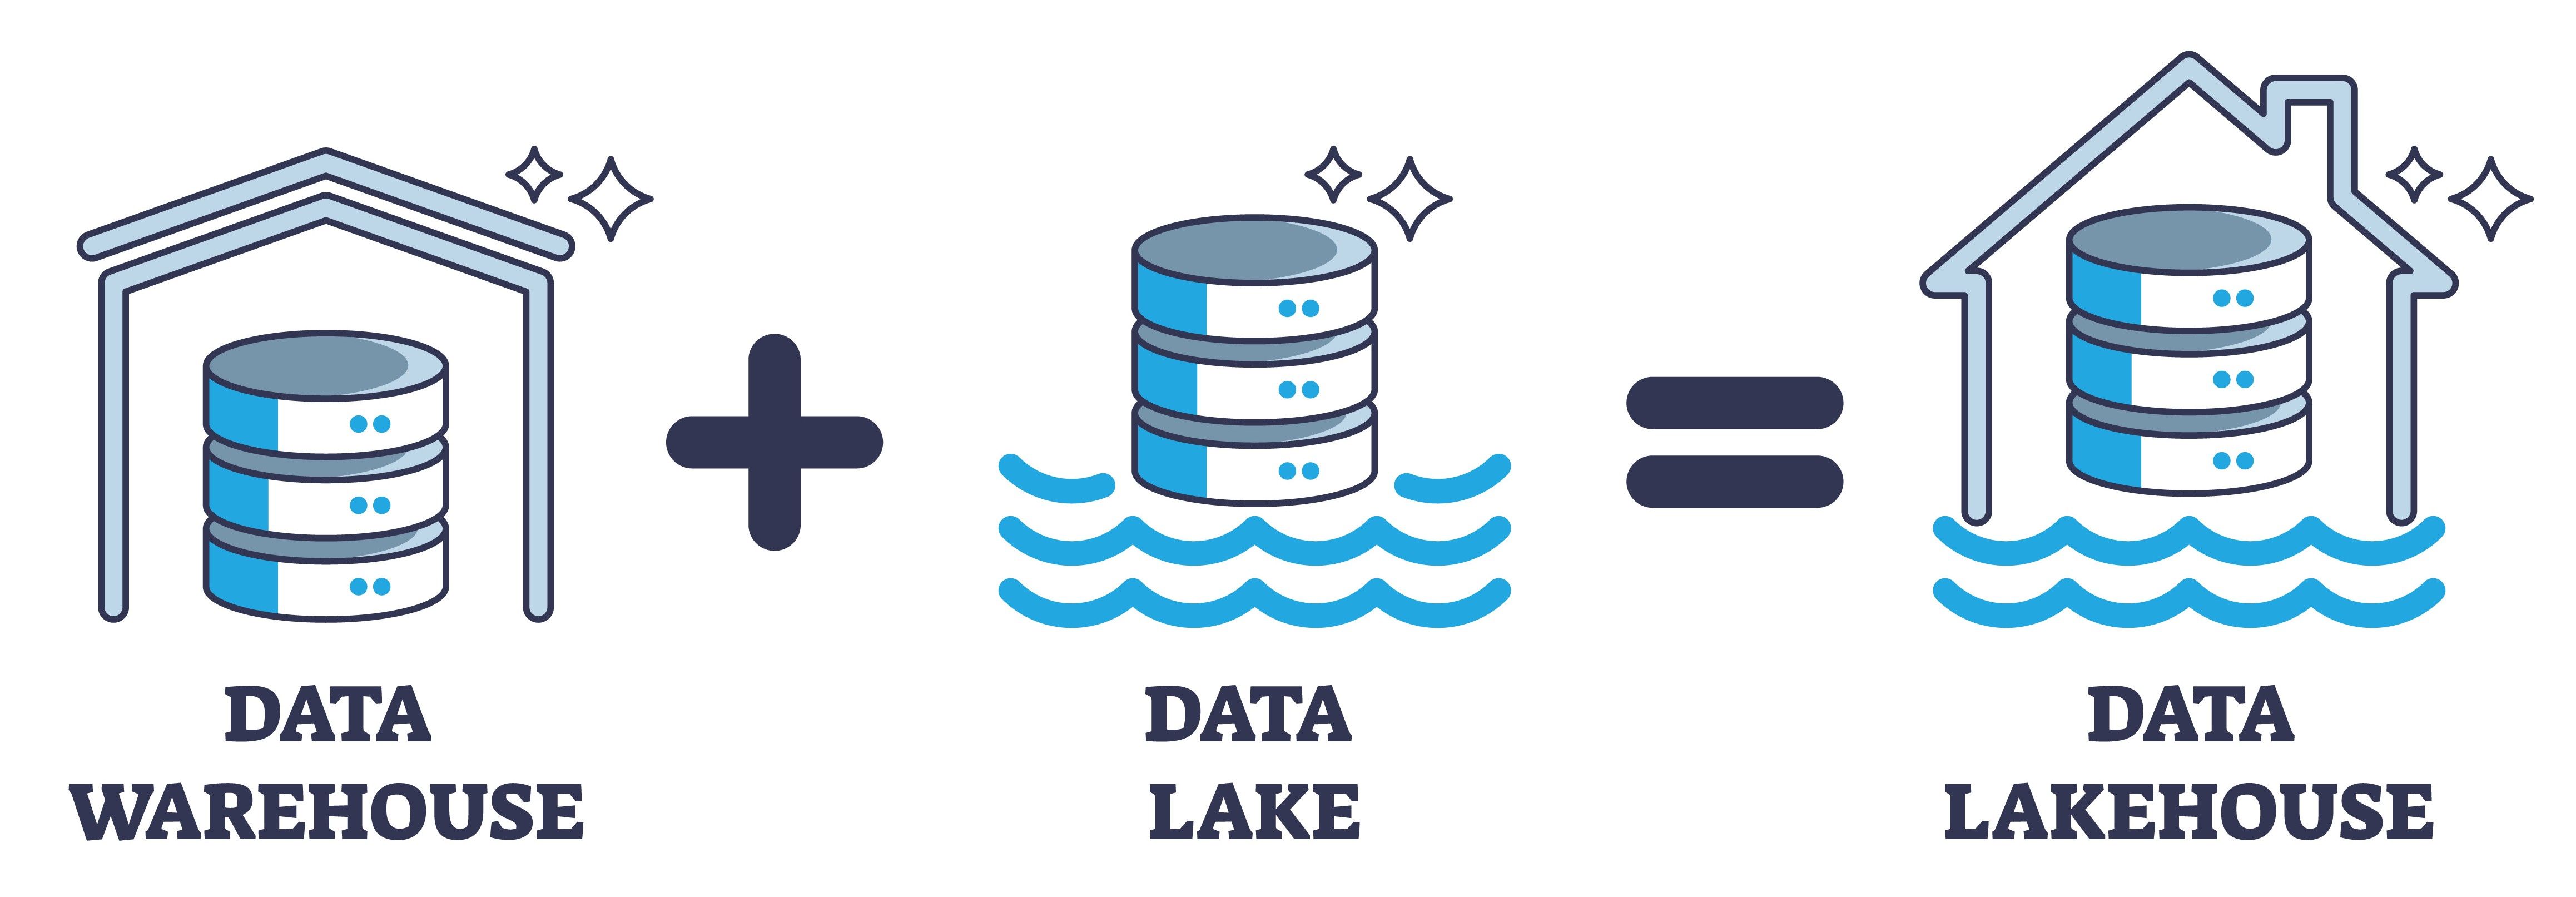
A data warehouse stores cleaned, structured data in a predefined relational schema, purpose-built for fast SQL queries, business intelligence, and consistent reporting. A data lakehouse stores structured, semi-structured, and unstructured data together on low-cost object storage, then adds a transactional metadata layer so the same data supports both BI and AI on one platform.
The split comes down to when structure is applied. A warehouse uses schema-on-write: data must conform to a fixed structure before it lands. That guarantees consistency and query performance, but it demands upfront design work and rejects anything that doesn't fit the model. A lakehouse supports schema-on-read alongside schema-on-write, so raw data can be ingested first and structured later. For AI teams that need direct access to granular, raw data for feature engineering and model training, that flexibility is the whole point.
Crucially, the lakehouse isn't a third silo. It uses open table formats such as Apache Iceberg, Delta Lake, and Apache Hudi to bring ACID transactions, schema enforcement, and time travel to data sitting in inexpensive cloud storage like Amazon S3 or Azure Blob. In effect, the lakehouse tries to keep the cost profile of object storage while adding the consistency, versioning, and table-level control enterprises expect from analytical databases.
How is a data lakehouse different from a data lake?
A data lake is best understood as low-cost storage for raw files. It can hold almost any format, but by itself, it doesn't behave like a database. Without a transaction layer, failed writes, inconsistent files, and record-level updates become difficult to manage.
A data lakehouse adds the metadata and governance layer that lakes lack. Open table formats track which files make up a table, enabling database-style operations directly on object storage. In short, a lakehouse is a data lake that has grown up enough for enterprise use.
Which architecture is better for enterprise AI and machine learning?
For most enterprise AI and machine learning workloads, the data lakehouse has the advantage, for three concrete reasons.
-
First, AI needs all data types. Models for fraud detection, computer vision, or document understanding consume images, sensor streams, logs, and text alongside structured records. A warehouse handles only the structured slice; a lakehouse handles the lot in one place.
-
Second, lakehouses integrate natively with ML frameworks such as TensorFlow and PyTorch, and with tools like Apache Spark, so data scientists can train models directly on the data without copying it into a separate environment. Every copy avoided removes a point of failure, a governance gap, and a cost line.
-
Third, AI workloads have a distinctive economic shape. Training jobs need heavy compute in short bursts; inference needs constant low-latency access. Because a lakehouse separates compute from storage, teams can spin up clusters only when training or batch inference runs, rather than paying for always-on infrastructure.
A warehouse still wins where the job is structured analytics: financial reporting, regulated dashboards, and predefined queries where consistency and mature BI-tool integration matter most.
Is a data lakehouse cheaper than a data warehouse?
Usually, yes, at scale, but the saving isn't free, and the honest answer depends heavily on which specific platforms are being compared. Publicly listed cloud storage rates give a useful anchor: Amazon S3 Standard storage runs roughly $21 to $23 per terabyte per month before volume discounts, while managed warehouse storage from providers like Snowflake is typically billed at a premium over raw object storage because it bundles in the platform's own storage management layer. That structural gap compounds quickly when an organization retains petabytes of training data or historical archives queried only occasionally.
The offset is engineering cost. A warehouse is largely a single-vendor product your analysts already know. A lakehouse stitches together open-source components, a table format, a query engine, a catalogue, and someone has to configure caching, partitioning, and file sizes, then maintain compatibility as each component updates on its own schedule. The rule of thumb: lakehouses tend to lower storage and compute costs but raise setup and skills costs. Any specific savings percentage quoted for a lakehouse migration should be checked against the actual platforms being compared and the workload profile involved, since the figure varies enormously by starting point and is often published by vendors with a direct commercial stake in one side of the comparison.
A useful warning sign that warehouse economics are breaking down: storage growing faster than 50% a year while query volumes stay flat, idle compute most of the day, and a finance team querying licensing bills that exceed six figures for relatively modest data volumes.
When should you choose a data warehouse over a data lakehouse?
A warehouse is still the cleaner choice when the workload is predictable: governed dashboards, finance reports, KPI tracking, regulatory reporting, and SQL-heavy analysis over well-modeled relational data. Warehouses are simpler to implement and maintain, which makes them a strong entry point for organizations earlier in their data maturity.
Choose a data lakehouse when you're building long-term AI capability, working with mixed data types, expecting rapid data growth, and willing to invest in the engineering skills to manage open components. The trade is higher initial complexity for far greater flexibility later.
The honest framing is that this is a spectrum of trade-offs, not a binary winner. The right answer depends on your data types, scale, governance requirements, and analytics maturity, not on which architecture is fashionable.
Do you have to replace your warehouse to adopt a lakehouse?
No, and this is the most important point for any large enterprise weighing the decision, and the one most vendors underplay. Enterprises don't need to abandon their warehouse on day one. A practical lakehouse strategy often starts by moving raw, semi-structured, and AI-heavy workloads into the lakehouse while preserving the warehouse for trusted BI and reporting. Because both read open formats, the transformed data is available to each without excessive duplication.
In practice, many mature enterprises run a hybrid. A general-purpose lake or lakehouse ingests everything; curated subsets feed business-unit warehouses for decision-making; and AI workloads run against the same governed data. This gives a single source of truth across BI and AI without maintaining two disconnected stacks, and it allows incremental migration rather than a single high-risk cut-over.
How do open table formats affect the decision?
Open table formats are what make a lakehouse viable, so they belong in the decision, not just the implementation. Apache Iceberg, Delta Lake, and Apache Hudi all add ACID transactions, schema evolution, and time travel to open file formats, but they suit different teams.
Iceberg is engine-agnostic and backed by contributors from many companies under the Apache Software Foundation, which suits large, read-heavy analytics across multiple engines and reduces the risk of single-vendor lock-in. Delta Lake, maintained by the Linux Foundation's Delta Lake project with deep roots in Databricks, is strongest for teams already centered on Spark and Databricks, particularly for real-time pipelines. The feature gap between them is narrowing as the ecosystems converge, so the practical question is which fits your existing engines and skills today, not which format wins in the abstract.
For enterprise AI specifically, the open format also future-proofs your context layer: your data stays in your own cloud, queryable by whichever AI tooling and agent runtime you adopt next, rather than trapped in a proprietary store.
What about data governance and compliance?
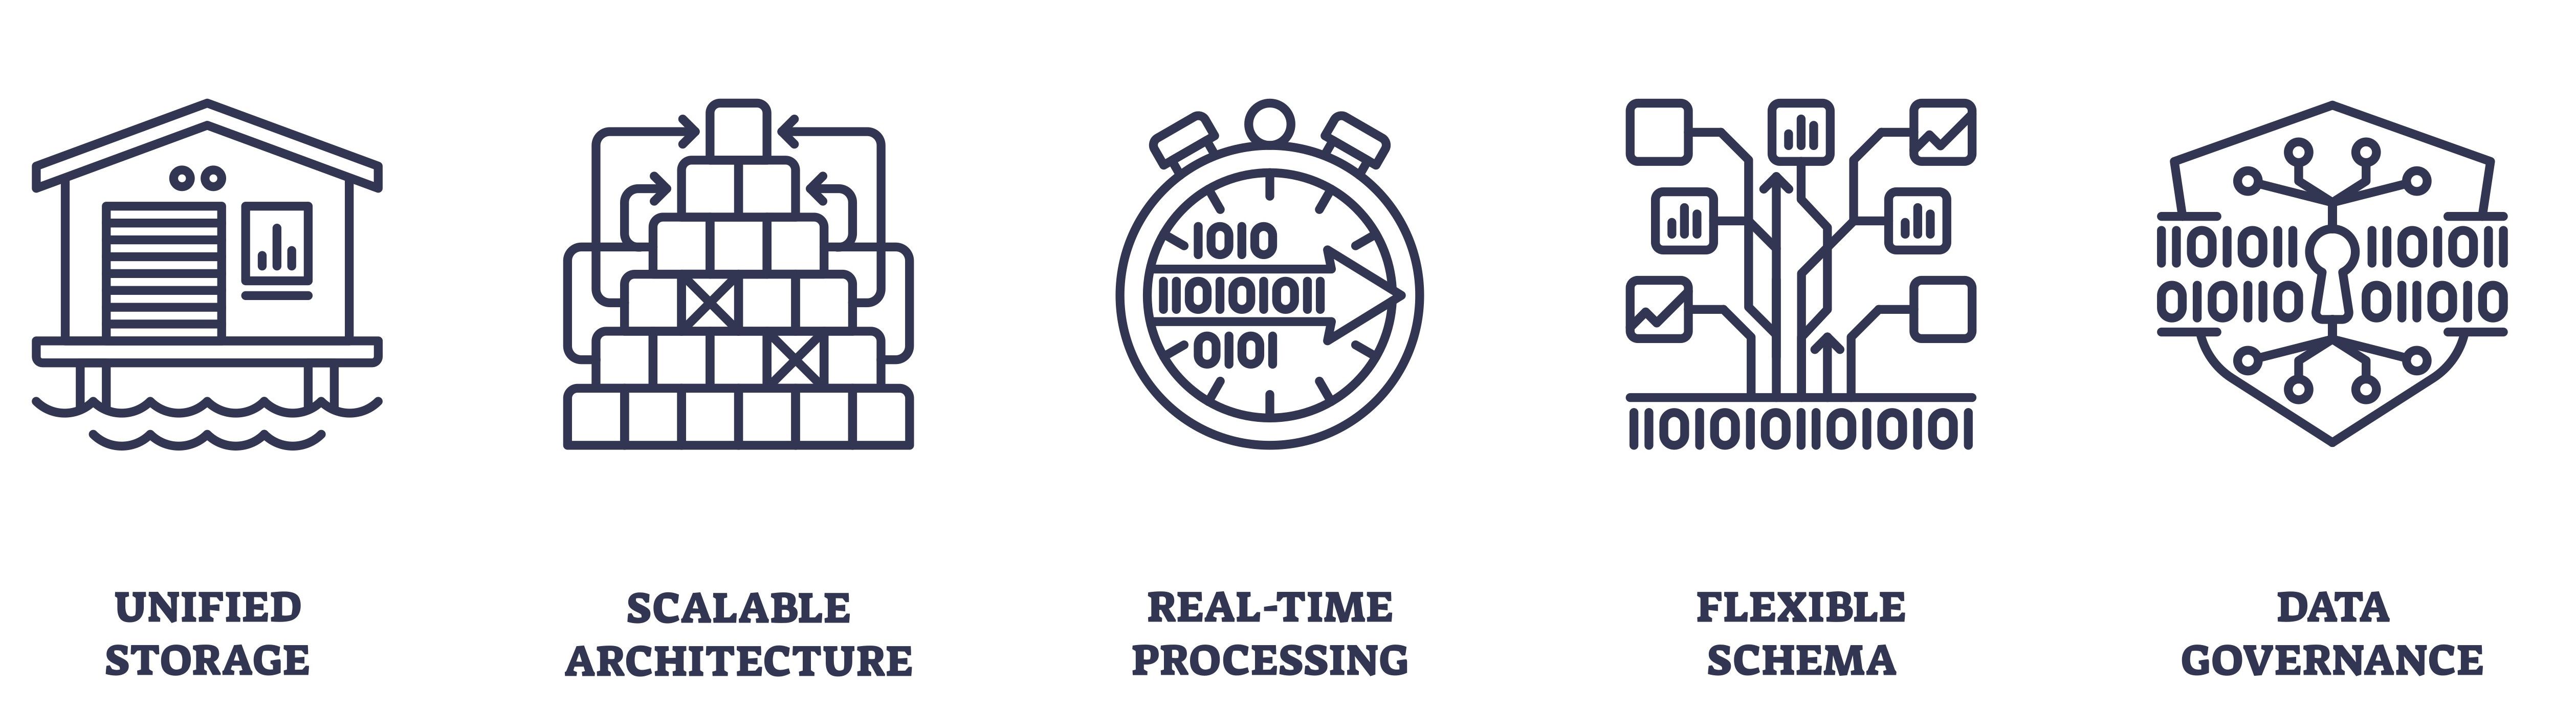
Governance is no longer a reason to default to a warehouse. Modern lakehouses deliver fine-grained access control, auditing, lineage, and encryption, and a unified governance layer can apply consistent policies across engines and formats. The caveat is that lakehouse governance has to be designed deliberately; organizations that defer it until later usually pay more retrofitting it than they would have spent building it upfront.
For regulated sectors, financial services, healthcare, the public sector, the governed lakehouse is increasingly the preferred route precisely because it keeps compliance, advanced analytics, and large-scale AI on one auditable platform. Deployment flexibility helps too: lakehouse platforms can run on-premises, hybrid, or multi-cloud, which matters where data residency rules constrain where information may sit.
The Bottom Line: How Should an Enterprise Decide?
Decide by workload and trajectory, not by label. Map how your teams ingest, transform, and activate data, then weigh four questions: What data types do you need? How fast is your data growing? What AI capabilities are you building over the next three years? Can your team manage open components?
Use a warehouse-led approach like Snowflake when your enterprise needs a governed, scalable, business-ready analytics foundation with strong BI, reporting, predictive analytics, and operational reliability. Use a lakehouse-led architecture when AI workloads require large-scale processing of raw, semi-structured, or unstructured data, open table formats, and deeper engineering control. For many enterprises, Tarento's recommended path is hybrid: keep Snowflake for trusted analytics and enterprise reporting, while using lakehouse patterns for raw data, AI pipelines, and high-volume engineering workloads.
Frequently Asked Questions
Is a data lakehouse the same as a data lake with extra features?
Functionally, yes, that's an accurate way to think about it. A data lakehouse adds a transactional metadata layer, using open table formats like Apache Iceberg or Delta Lake, on top of the same low-cost object storage a data lake uses. That layer is what enables database-style operations, schema enforcement, and time travel directly on files that would otherwise just be raw, unmanaged storage.
Which is cheaper: Snowflake or a data lakehouse?
It depends on workload shape more than platform choice. Lakehouses generally reduce storage costs at scale because they run on object storage rather than premium-priced managed warehouse storage, but they raise engineering and skills costs since open components need to be configured and maintained. A warehouse like Snowflake reduces engineering overhead but costs more per terabyte at scale. Any specific savings percentage should be checked against the actual workload and platforms being compared, since vendor-published figures often reflect a specific product comparison rather than a general rule.
Can I use both a data warehouse and a data lakehouse at the same time?
Yes, and most mature enterprises do exactly this. A common pattern keeps a warehouse like Snowflake for governed BI and reporting while running a lakehouse for raw, AI-heavy, and rapidly growing data, with open table formats allowing both to read the same underlying data without excessive duplication.
Does adopting a lakehouse mean giving up data governance?
No. Modern lakehouse platforms support fine-grained access control, auditing, lineage tracking, and encryption comparable to a traditional warehouse. The difference is that lakehouse governance has to be designed deliberately from the start rather than assumed, since it isn't bundled into a single vendor's managed service the way warehouse governance typically is.
What's the biggest risk in migrating from a data warehouse to a data lakehouse?
Underestimating the engineering and skills investment required to manage open-source components like table formats, query engines, and catalogs, which don't come with the single-vendor support model a warehouse provides. The realistic risk isn't the migration itself, it's assuming a lakehouse runs itself the way a managed warehouse does.
Turn your data architecture into an AI advantage. Partner with Tarento to modernise your Snowflake environment, optimise data pipelines and build a governed foundation for enterprise AI. Speak to a Snowflake Expert | Learn more

AI agents in the supply chain: building the foundation that makes them work